

Loading…
Loading…
Loading…
OCR GCSE Geography B · J384
OCR J384 · 9.2 Graphical Techniques Check the specification (PDF) (opens in a new tab)
Geographical graphs turn numbers into patterns that can help us investigate places and processes. Reading them involves more than finding the tallest bar: we need to extract values, identify relationships, interpret their meaning and judge how much confidence to place in a conclusion.
First read the title, which identifies the subject, location or period. Then check the key, the variables shown and their units. On an ordinary graph, read both axes and work out the value of each scale interval. Check whether either axis begins above zero: a shortened scale can make a small difference look dramatic.
Some charts need a different reading route. A pie chart uses its key to identify categories and shows their shares of a whole. A graph with two vertical axes requires you to match each dataset to the correct scale and unit. These checks establish what the values mean before you interpret them.
To extract a value from a line graph, locate the position on the horizontal axis, trace vertically to the line, then horizontally to the vertical axis. If the point falls between scale markings, give an appropriately approximate reading rather than false precision.
Begin with the overall pattern: is the variable generally increasing, decreasing or remaining stable? Then add useful detail, such as the highest and lowest values, where change is fastest, and any exceptions. Analysis involves examining these patterns, comparisons and relationships rather than simply copying a sequence of numbers.
The graph below demonstrates this method. It does not represent measurements from a real town.
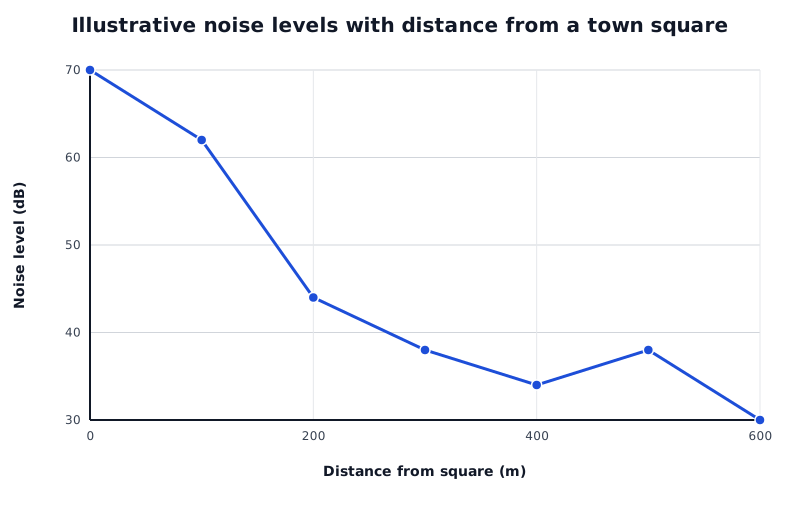
Noise generally decreases with distance, but rises at 500 m.
Data for Illustrative noise levels with distance from a town square
| Series | Distance from square (m) | Noise level (dB) |
|---|---|---|
| Illustrative noise readings | 0 | 70 |
| Illustrative noise readings | 100 | 62 |
| Illustrative noise readings | 200 | 44 |
| Illustrative noise readings | 300 | 38 |
| Illustrative noise readings | 400 | 34 |
| Illustrative noise readings | 500 | 38 |
| Illustrative noise readings | 600 | 30 |
Noise generally decreases with distance from the square, falling from 70 dB at 0 m to 30 dB at 600 m. The values therefore span 30–70 dB, with a numerical range of dB. Distinguish this difference from the distance covered by the survey, which is 0–600 m.
The decrease is not uniform. Between 100 m and 200 m, noise falls by 18 dB, compared with only 4 dB between 300 m and 400 m. Because these intervals cover the same distance, they can be compared directly: the first decrease is faster. For unequal intervals, compare change per unit of distance or time, rather than just the size of the change.
There is also an anomaly: noise rises from 34 dB at 400 m to 38 dB at 500 m before falling again. Identifying this exception gives a more accurate account than saying that noise decreases at every point.
A useful memory aid is GRaDE: general trend, range or coverage, data quotations, and exceptions. It helps organise an evidence-based description, but you do not need to force an exception into a dataset that has none.
When a graph contains several datasets, identify similarities and differences directly. Ask whether they follow the same trend, which has higher values, whether their peaks occur together, and whether the gap between them changes.
For example, if two locations have rainfall totals of 80 mm and 50 mm in the same month, the first has 30 mm more rainfall. This is a direct comparison. Describing each location separately makes the relationship less clear.
Check that comparisons are fair. A total for a whole year cannot be compared directly with a total for one month. Likewise, a population count and a percentage answer different questions: the percentage describes a share of the population, not its absolute size.
A scatter graph plots paired values for two variables. Positive correlation means that higher values of one tend to accompany higher values of the other. With negative correlation, higher values of one tend to accompany lower values of the other. If there is no clear relationship, there is no apparent correlation.
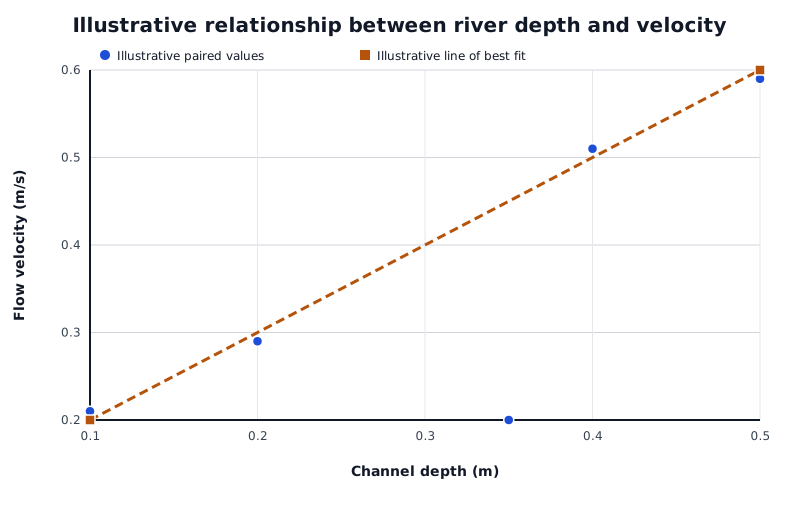
Paired values and a line of best fit. The low point at 0.35 m is anomalous.
Data for Illustrative relationship between river depth and velocity
| Series | Channel depth (m) | Flow velocity (m/s) |
|---|---|---|
| Illustrative paired values | 0.1 | 0.21 |
| Illustrative paired values | 0.2 | 0.29 |
| Illustrative paired values | 0.35 | 0.2 |
| Illustrative paired values | 0.4 | 0.51 |
| Illustrative paired values | 0.5 | 0.59 |
| Illustrative line of best fit | 0.1 | 0.2 |
| Illustrative line of best fit | 0.5 | 0.6 |
These constructed river data show a positive relationship: greater channel depth generally accompanies greater flow velocity. Most points lie close to the line of best fit, suggesting a fairly strong relationship. Strength depends on how closely points follow the trend, not on how steep the line is.
The point at a depth of 0.35 m and a velocity of 0.20 m/s lies well below the general pattern. An anomaly might reflect a measurement error or a genuine local difference, such as another unmeasured variable. It should be investigated, not automatically removed.
A relationship is not proof that one variable causes the other. To interpret it geographically, connect the pattern to relevant processes and consider other influences. Similarly, the rise in noise at 500 m in the first graph could suggest an additional nearby noise source, but the graph alone cannot establish what that source is.
A line of best fit helps estimate values that were not measured. On the river graph, start at a depth of 0.30 m, trace upwards to the trend line, then across to the velocity axis. The estimated velocity is 0.40 m/s. This is interpolation, because 0.30 m lies within the plotted depth range.
Extending the same trend to a depth of 0.60 m would give an estimated velocity of 0.70 m/s. This is extrapolation, because it goes beyond the plotted depth range of 0.10–0.50 m. It is less secure: the relationship may change outside the available data. Neither estimate is a new measured observation.
Evaluation means judging the usefulness and limitations of the evidence. Separate the way a graph presents information from the quality of the underlying data.
For presentation, check whether labels, units, scales and the key make the graph clear. A truncated axis may exaggerate apparent differences; a broad scale may conceal small ones. Read the numbers rather than relying only on visual impressions.
For the data, consider how many observations were collected, where and when they were taken, and how accurately they were measured. Noise readings taken once during a busy afternoon might describe that moment well, but would not establish typical conditions throughout the week. Repeating readings at different times would provide stronger evidence for that wider conclusion.
Finish with a judgement proportionate to the evidence. A clear trend may support a conclusion about the sampled locations or period without justifying a claim about every place or every time. The reading methods demonstrated here transfer to real geographical graphs.
Connect patterns to relevant geographical processes without claiming unsupported causes. Judge presentation, sample size, timing, location coverage and measurement accuracy. Explain how a limitation restricts the conclusion.
Read the title, key, axes, units and scale before quoting values. Check whether the scale starts at zero.
Support a pattern with selected figures and units rather than listing every value.
When comparing datasets, make direct comparisons over the same period, distance or category.
Describe what the graph shows before suggesting an explanation. Correlation alone does not prove cause and effect.
Treat interpolated and extrapolated values as estimates. Extrapolation is usually less secure.
Evaluate a specific limitation and explain how it affects the conclusion; do not simply say that the data is unreliable.
It can see this note and what your specification asks for.
Answers are free with an account.
1 free note left this week
Get more free notesYour answer sets when this note comes back for review, or marks it complete.
Was this note helpful?
Log in to tell us whether it helped, or to report a problem.
Last updated
Trend
An overall pattern of increase, decrease or stability in a dataset.
Anomaly
A value that does not follow the general pattern of a dataset.
Range
The difference between the highest and lowest values in a dataset: .
Correlation
A relationship between two variables: positive when they tend to increase together, negative when one tends to decrease as the other increases.
Line of best fit
A line showing the overall relationship between plotted points on a scatter graph.
Interpolation
Estimating an unknown value within the range of known data.
Extrapolation
Estimating an unknown value beyond the range of known data by extending its trend.
Accuracy
How close a measurement is to the true value.
Reliability
How consistently a study produces similar results when repeated under comparable conditions.
Put your knowledge into practice — try past paper questions for Geography B
Trend
An overall pattern of increase, decrease or stability in a dataset.
Anomaly
A value that does not follow the general pattern of a dataset.
Range
The difference between the highest and lowest values in a dataset: .
Correlation
A relationship between two variables: positive when they tend to increase together, negative when one tends to decrease as the other increases.
Line of best fit
A line showing the overall relationship between plotted points on a scatter graph.
Interpolation
Estimating an unknown value within the range of known data.
Extrapolation
Estimating an unknown value beyond the range of known data by extending its trend.
Accuracy
How close a measurement is to the true value.
Reliability
How consistently a study produces similar results when repeated under comparable conditions.