

Loading…
Loading…
Loading…
Edexcel GCSE Mathematics · 1MA1
Edexcel 1MA1 · P5 Check the specification (PDF) (opens in a new tab)
Probability describes how likely an outcome is. Sometimes it can be calculated from a model. For a fair coin, heads and tails are equally likely, so
This is a theoretical probability: it follows from the assumption that the coin is fair. The corresponding theoretical probability distribution assigns probability to heads and to tails.
We can also estimate probability by carrying out an experiment. If a coin produces 23 heads in 40 tosses, its relative frequency of heads is
This is an empirical probability, because it comes from observed results. It need not equal the theoretical probability exactly.
Chance creates random variation. One set of 20 tosses might contain 13 heads, while another set of 20 tosses might contain only 8. Neither result is impossible for a fair coin, and the difference does not by itself show that the coin has changed.
Small samples are particularly variable because each result has a large effect. After 10 tosses, one additional head changes the relative frequency by much more than one additional head after 1,000 tosses.
This is also why an actual outcome, such as the profit from a probability game, may differ from its expected value. The expected value describes a long-run average, not a guaranteed result from a small number of plays.
As an unbiased experiment is repeated many times under the same conditions, its empirical probability generally becomes more stable and tends towards the underlying theoretical probability. For a fair coin, the relative frequency of heads tends towards .
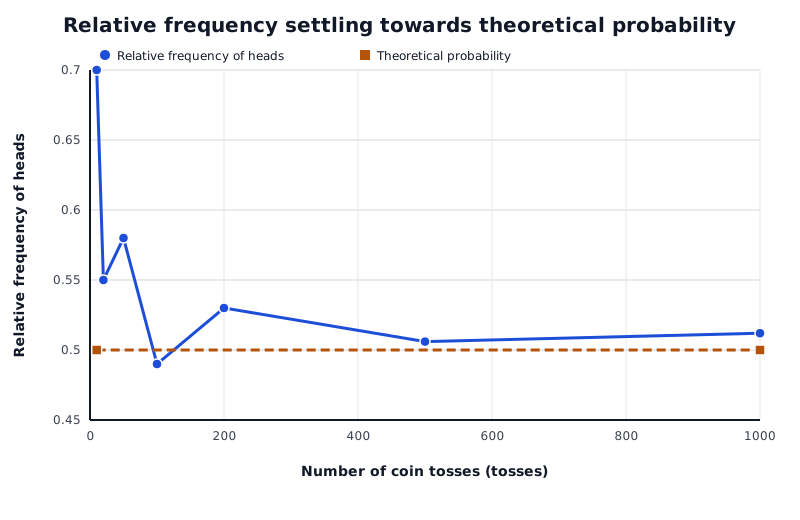
Results can fluctuate above and below 0.5. As the number of trials increases, the relative frequency generally becomes more stable around the theoretical probability; it need not move closer after every trial.
Data for Relative frequency settling towards theoretical probability
| Series | Number of coin tosses (tosses) | Relative frequency of heads |
|---|---|---|
| Relative frequency of heads | 10 | 0.7 |
| Relative frequency of heads | 20 | 0.55 |
| Relative frequency of heads | 50 | 0.58 |
| Relative frequency of heads | 100 | 0.49 |
| Relative frequency of heads | 200 | 0.53 |
| Relative frequency of heads | 500 | 0.506 |
| Relative frequency of heads | 1000 | 0.512 |
| Theoretical probability | 10 | 0.5 |
| Theoretical probability | 1000 | 0.5 |
The movement is not necessarily smooth. The relative frequency can move away from the theoretical value temporarily, even after more trials. The important long-run pattern is that fluctuations usually become smaller relative to the total number of trials. A larger sample therefore generally gives a more reliable estimate, but it does not guarantee an exact match.
The same idea applies to a whole probability distribution. For a fair six-sided die, the empirical proportion for each face tends towards as the number of rolls increases.
Increasing sample size helps only when the data are collected fairly. An unbiased experiment should not systematically favour particular outcomes. Conditions should be kept consistent, every result should be recorded, and the stopping point should not be chosen because a convenient result has just appeared.
For a population survey or inspection, the people or objects sampled should represent the population of interest. A very large but badly selected sample can still give a misleading estimate of a population characteristic.
For example, to estimate the proportion of faulty items in a delivery, selecting items randomly from throughout the delivery is more representative than testing only the easiest box to reach.
Compare relative frequencies, not just numbers of successes. Suppose one experiment records 34 heads and 8 tails, while another records 120 heads and 40 tails. Their estimates are
and
The second estimate is based on 160 trials rather than 42, so it is normally the more reliable individual estimate. The first experiment having a larger relative frequency does not make it better evidence.
If several people test the same object under the same conditions, use all the raw results to obtain the strongest estimate. In the Edexcel example, the four experiments contain 300 heads and 100 tails altogether, so
Combining the counts correctly gives more weight to larger experiments. Simply averaging the four separate relative frequencies would give a small experiment the same influence as a large one.
When a theoretical model is known, compare it with the experimental distribution. Large differences in a small sample may be explained by chance, whereas persistent differences in a large, unbiased sample may suggest that the model or its assumptions are unsuitable.
When the theoretical probability is unknown—perhaps because a coin is biased—the relative frequency from a large unbiased sample can be used as an estimate. The conclusion should remain appropriately cautious: it is an estimate supported by the available data, not certainty about what the next trial will produce.
Use relative frequency as an estimate of an unknown probability.
Prefer the estimate based on more trials. If experiments used the same conditions, combine their raw data:
Do not simply average relative frequencies from differently sized samples.
Actual frequencies may differ from expected frequencies, especially for a small number of trials. A large sample improves reliability only if its selection or experimental method is unbiased.
When comparing experiments of different sizes, calculate relative frequencies; raw frequencies are not directly comparable.
For the best estimate from several experiments under the same conditions, combine the numbers of successes and combine the numbers of trials. Do not take an unweighted mean of the separate relative frequencies.
Do not claim that the relative frequency must get closer to the theoretical probability after every extra trial. Say that it generally becomes more stable and tends towards the theoretical value as the sample size increases.
Expected results are predictions, not guarantees. Actual frequencies can differ because of random variation.
If asked to justify which result gives the best estimate, identify the larger sample size and link it to reduced random variation.
It can see this note and what your specification asks for.
Answers are free with an account.
1 free note left this week
Get more free notesYour answer sets when this note comes back for review, or marks it complete.
Was this note helpful?
Log in to tell us whether it helped, or to report a problem.
Last updated
Empirical probability
A probability found from the results of an experiment or observed data.
Relative frequency
The proportion of trials in which an outcome occurs: frequency of the outcome divided by the total number of trials.
Theoretical probability
A probability calculated from a mathematical model, such as equally likely outcomes for a fair die.
Probability distribution
The complete set of probabilities assigned to all possible outcomes.
Unbiased sample
A sample selected or produced without systematically favouring particular outcomes or members of the population.
Random variation
Differences between experimental results caused naturally by chance.
Put your knowledge into practice — try past paper questions for Mathematics
Empirical probability
A probability found from the results of an experiment or observed data.
Relative frequency
The proportion of trials in which an outcome occurs: frequency of the outcome divided by the total number of trials.
Theoretical probability
A probability calculated from a mathematical model, such as equally likely outcomes for a fair die.
Probability distribution
The complete set of probabilities assigned to all possible outcomes.
Unbiased sample
A sample selected or produced without systematically favouring particular outcomes or members of the population.
Random variation
Differences between experimental results caused naturally by chance.